






































Artificial intelligence is increasingly moving from chatbots that answer questions to software agents that can take actions. That shift creates a less visible problem: agents have to make thousands of small decisions before they complete a task.
TypeSafe AI is targeting that problem with Jev, a new model designed specifically for rapid, structured decision-making rather than traditional text generation.
TypeSafe introduced Jev on September 15, 2026, describing it as its first “System One Model.” The company says the model is designed to make decisions that software can consume directly, including choices, scores and probabilities.
Jev Is Designed for Decisions, Not Long-Form Text
A conventional large language model is often asked to generate an answer even when an AI application only needs a simple decision.
For example, an agent may need to determine:
- Which tool should be called next?
- Should a failed operation be retried?
- Is a requested action safe?
- Should a transaction be escalated to a human?
- Which model should handle the next step?
- How should an item be scored?
Jev is designed around these bounded decisions. Instead of producing a paragraph and forcing software to interpret it, the model can return a structured result that fits a predefined schema.
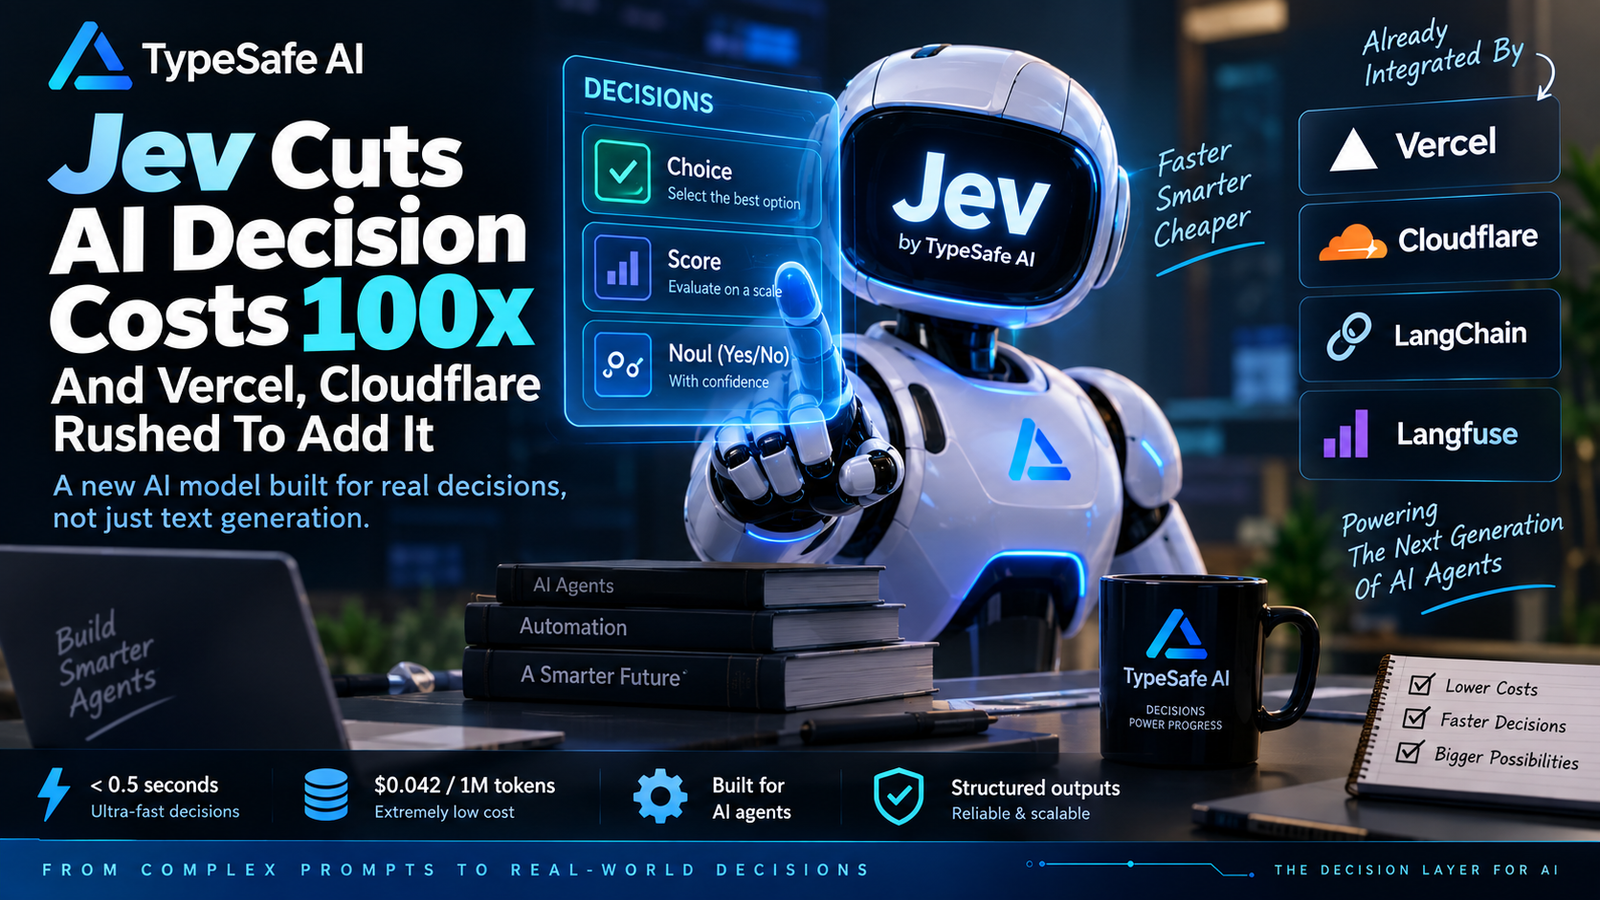
TypeSafe says Jev can return a Choice, a Score, or a Boolean/yes-no probability, along with calibrated confidence. Its architecture also allows multiple questions to be evaluated in parallel.
Why This Matters for AI Agents
The economics of AI agents are different from those of a chatbot.
A chatbot might make a handful of model calls during a conversation. An autonomous agent can make many calls while planning, selecting tools, checking results and deciding what to do next.
If every small decision requires a comparatively expensive general-purpose model, those costs can accumulate quickly.
Jev is intended to serve as a specialized decision layer inside that workflow. Vercel describes the model as something to use alongside generative models rather than as a replacement for them: general LLMs remain useful for prose and code, while Jev can handle bounded evaluations and decisions.
Jev’s Pricing and Speed Claims
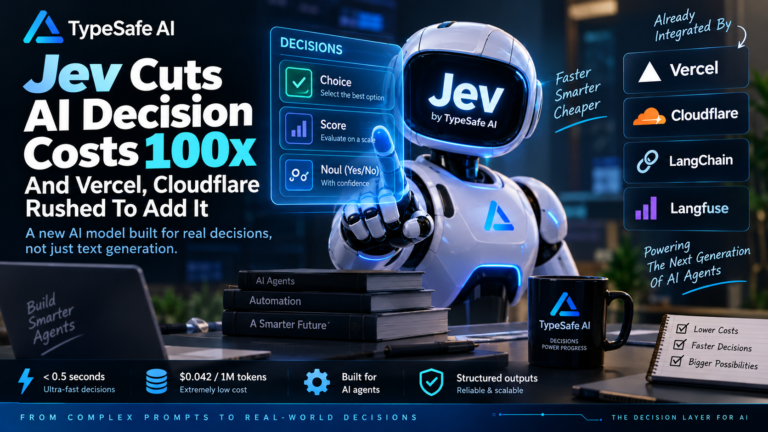
TypeSafe’s current website lists Jev at $42 per billion input tokens, equivalent to about $0.042 per million input tokens. The company positions that pricing as dramatically below many general-purpose models.
The bigger claim is not simply lower price, but the combination of low cost and low latency.
Vercel says TypeSafe reported Jev as up to 193.6 times faster and 444.6 times cheaper than LLMs in its workflow evaluations. Vercel later summarized those figures as roughly 194 times faster and 445 times cheaper.
Those figures should be treated as benchmark-specific claims, not as a universal guarantee that every AI workload will see the same improvement.
How Jev Returns an Answer
Jev is built around typed decisions.
A developer can define the possible outcomes or scoring framework and send the relevant application state to the model. Jev then evaluates the question against that information.
For a routing decision, the output could be a choice among several tools. For a risk workflow, it could return a score or probability. For a safety check, it could provide a yes/no probability.
TypeSafe says its schema-matching approach prevents the model from returning an option outside the choices declared by the developer. That makes the output easier for software systems to consume directly.
Important distinction: a constrained output does not automatically mean a correct output. The model can still interpret evidence incorrectly, which is why confidence thresholds and human review remain important in higher-risk workflows.
Vercel Adds Jev to AI Gateway
Vercel moved Jev into its AI Gateway shortly after the model launched.
According to Vercel’s September 16 changelog, Jev supports typed Choice, Score and Boolean answers and can evaluate multiple questions in parallel. Vercel also highlighted TypeSafe’s performance and cost claims for workflow evaluations.
Vercel subsequently said Jev became the fastest-adopted model in the history of its AI Gateway, although that is a Vercel statement about its own platform adoption rather than an independent industry measurement.
Cloudflare Brings Jev to Its AI Platform
Cloudflare has also added typesafe/jev to its AI model ecosystem.
Cloudflare’s documentation describes Jev as a structured evaluation model with a 32K context window. Its examples include decisions around refund reviews and account risk, illustrating how the model can fit into application workflows where a final structured decision matters more than generated prose.
The integration means developers working inside Cloudflare’s AI infrastructure can use Jev as a specialized evaluation component rather than building every decision step around a general-purpose generative model.
LangChain Sees Jev as an Agent Tool
LangChain has also published integrations and examples involving Jev.
In a September 17 article, LangChain described Jev as fundamentally different from a traditional LLM because it does not generate text. The company highlighted potential uses such as model routing and tool-call guardrails, while citing TypeSafe’s reported speed and cost advantages on classification tasks.
LangChain later tested Jev as a judge for agent evaluations. In that narrow experiment, LangChain reported an average Jev call time of about 0.44 seconds and a cost of approximately $0.00035 per call, compared with $28.17 for the Claude setup it tested. LangChain also emphasized that the experiment was early and narrow and that cheaper evaluation can amplify mistakes if quality controls are ignored.
Jev Could Be Useful in Several Agent Workflows
The model’s design points toward a range of practical applications.
Model routing: An agent can evaluate which model should handle a task based on complexity, cost or requirements.
Tool selection: Jev can help determine which available tool should be called next.
Retry decisions: Instead of automatically sending every failure back to an expensive LLM, an application can use a smaller decision layer to determine whether another attempt makes sense.
Safety checks: An agent can evaluate whether an action should proceed automatically or be escalated for human review.
Risk scoring: Financial, operational or account-related workflows can use structured scores or probabilities.
Agent evaluation: Jev can act as a fast judge in selected evaluation pipelines.
These are examples of where a specialized decision model can complement a generative model rather than replace it.
TypeSafe Raises $40 Million Seed Round
The launch also arrived with significant venture backing.
DCVC announced on September 15 that it was leading a $40 million Series Seed investment in TypeSafe. The investment is aimed at supporting the company’s work on models optimized for automation.
TypeSafe was founded by Diogo Almeida, with co-founders Erik Gafni and Sasha Sheng. The company says Almeida previously worked at OpenAI on instruction-following research before the team spent two years working in stealth.
The funding gives TypeSafe capital to develop Jev and the broader “System One” approach as AI applications increasingly rely on automated decision-making.
Why the Name Jev Matters
The name comes from economist William Stanley Jevons, associated with the Jevons paradox.
The basic economic idea is that when a resource becomes more efficient or cheaper to use, demand for that resource can sometimes increase rather than decrease.
TypeSafe is applying that concept to AI decision-making: if intelligent decisions become sufficiently inexpensive and fast, developers may use them in far more places inside software systems.
That could mean more frequent checks, more sophisticated routing and more autonomous workflows rather than simply lower AI bills.
Jev Is Not a Replacement for General AI Models
One of the most important points for developers is that Jev occupies a different role from a conventional LLM.
A generative model remains useful when an application needs:
- Long-form writing
- Code generation
- Open-ended reasoning
- Conversational responses
- Complex synthesis
Jev is aimed at cases where the application already knows what decision needs to be made and wants a structured answer.
The distinction makes Jev closer to a specialized decision engine than a general-purpose chatbot.
The Accuracy Question Still Matters
Lower latency and lower cost only matter if the resulting decisions are reliable enough for the application.
A typed response can be perfectly valid according to a schema while still being the wrong decision. That is particularly important for financial, security, safety or customer-impacting workflows.
TypeSafe’s approach includes calibrated probabilities and confidence signals, which can allow developers to establish thresholds for autonomous action versus human review. Its own platform documentation emphasizes this threshold-based approach.
Developers therefore still need evaluation datasets, monitoring, fallback logic and appropriate human oversight for consequential decisions.
What Jev Could Mean for AI Agent Economics
The broader significance of Jev is less about one model being cheaper and more about the architecture of AI software.
If agents can delegate small decisions to a specialized model costing a fraction of a general-purpose LLM, developers could potentially increase the number of automated decisions performed inside an application.
That could change how AI agents are designed: a large generative model may handle complex reasoning, while specialized decision models handle the many smaller choices surrounding it.
Vercel, Cloudflare and LangChain integrating Jev shortly after its launch shows that major developer platforms are already experimenting with this architecture.
The next question is whether the early speed and cost advantages hold across a much wider range of real-world workloads while maintaining the accuracy developers need.